Varying Real Images with Stable Diffusion
Stable Diffusion is a large pretrained image generator. Instead of training a model ourselves (as in the DCGAN notebook), we use it to produce variations of real images: similar texture and structure, but not identical.
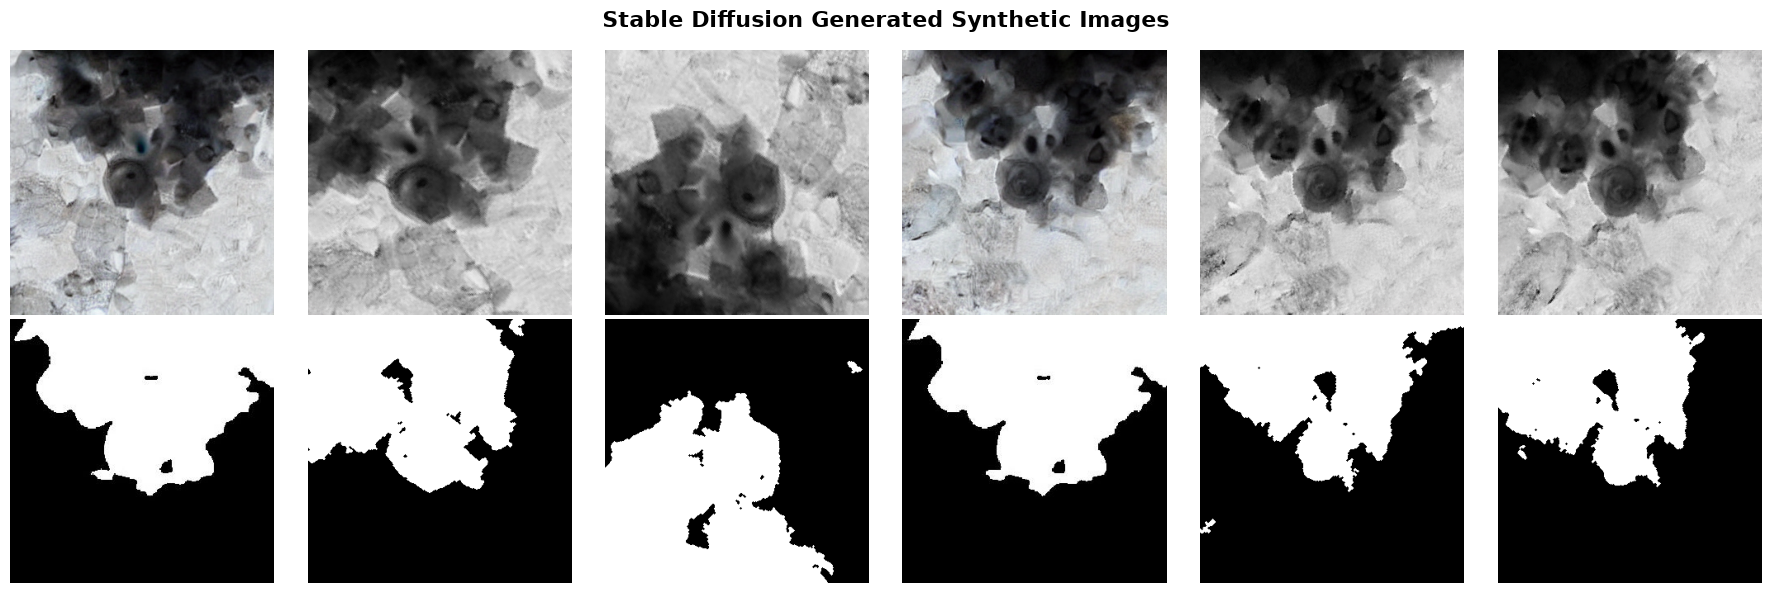
This notebook applies Stable Diffusion to frames of an in-situ TEM video of SiO₂ lithiation and shows the generated images with their masks.
JuSPICE Modules and Classes
juspice.io:SPICEData,load_data,save_datajuspice.synth_data_module:ConfigLoader,SynthGenerationAccessor(viaspice.synth_generation)juspice.tracking:Tracker
[1]:
from juspice.tracking import Tracker

tracker = Tracker(
    include_metadata=True, notes='Stable diffusion synthetic data generation'
)

tracker.recording_start()
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/tqdm/auto.py:21: TqdmWarning: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
  from .autonotebook import tqdm as notebook_tqdm
[2]:
# --------- Block 0: Setup ----------

# Standard library
from pathlib import Path
import sys
import os
import json
import logging
import shutil

# Third-party
import numpy as np
import matplotlib.pyplot as plt

try:
    import torch
    _torch_available = True
except ImportError:
    torch = None
    _torch_available = False
    print("WARNING: torch is not installed. Device selection will default to 'cpu'.")

# JuSPICE
from juspice.io import SPICEData, load_data, save_data
from juspice.synth_data_module import ConfigLoader

# Paths
try:
    notebook_dir = Path(__file__).resolve().parent
except Exception:
    notebook_dir = Path.cwd()

cur = notebook_dir
repo_root = None
for _ in range(6):
    if (cur / 'juspice').exists() or (cur / 'pyproject.toml').exists():
        repo_root = cur
        break
    if cur.parent == cur:
        break
    cur = cur.parent
if repo_root is None:
    repo_root = notebook_dir
if str(repo_root) not in sys.path:
    sys.path.insert(0, str(repo_root))

# Logging configuration
logging.basicConfig(
    level=logging.INFO,
    format='%(asctime)s - %(levelname)s - %(message)s',
    datefmt='%Y-%m-%d %H:%M:%S',
)
[3]:
tracker.recording_stop()
Settings
We choose a device and load the SDiff parameters from notebooks_parameters.yaml.
[4]:
tracker.recording_start()
[5]:
# --------- Block 1: Config and device ----------

_mps_available = (
    torch is not None
    and hasattr(torch.backends, 'mps')
    and torch.backends.mps.is_available()
)
if torch is not None and torch.cuda.is_available():
    device = 'cuda'
elif _mps_available:
    device = 'mps'
else:
    device = 'cpu'
logging.info(f'Using device: {device}.')

config_path = os.path.join(repo_root, 'notebooks', 'notebooks_parameters.yaml')
config = ConfigLoader(config_path)
logging.info(f'Configuration loaded from: {config_path}')

dataset = 'SiO2_lithiation'
method_name = 'SDiff'
N_images = 10
force = False
20:08:2026 18:25:50 - Using device: mps.
20:08:2026 18:25:50 - Configuration loaded from: /Users/amir/GIT_repositories/juspice_pre_release/notebooks/notebooks_parameters.yaml
[6]:
tracker.recording_stop()
How it works
A diffusion model (Ho et al., 2020) [34] learns to remove noise from images. To create an image, it starts from noise and removes it step by step. Stable Diffusion (Rombach et al., 2022) [35] does this on a compressed version of the image (its latent representation), which is much faster than working on every pixel.
JuSPICE uses the image-to-image mode: a real image is partly noised and then denoised again, guided by a text prompt. The less noise is added, the closer the result stays to the original.
Parameter |
Effect |
|---|---|
|
amount of noise added: 0 returns the input unchanged, 1 ignores it |
|
how strongly the text prompt steers the result |
|
text describing the desired image |
|
number of frames per synthetic sequence and how much they differ |
The mask of each input image is copied to its generated images. This is only valid if the objects stay in place, which is why the configuration uses a low strength (0.1). The generated images are variations of real data, not new measurements.
Requirements: the diffusers library [16] with a matching huggingface_hub, and ideally a GPU with at least 8 GB of memory (a CPU is very slow). The first run downloads about 5 GB of model weights into Pretrained_models/stable_diffusion/.
We now load one training image as the starting point and generate the images.
[7]:
tracker.recording_start()
[8]:
# --------- Block 2: Initialize and generate ----------

# Load one training image as the SPICEData entry point / history anchor —
# spice.synth_generation.generate() doesn't transform spice.data itself
# (it produces a brand-new dataset), but the returned dataset shares this
# object's history lineage, so the provenance reads "generated from this
# reference training set".
dataset_params = config.get_dataset_params(dataset)
training_images_dir = os.path.join(repo_root, dataset_params['training_images_dir'])
_img_exts = ('.png', '.jpg', '.jpeg', '.tif', '.tiff')
_seed_candidates = sorted(
    f for f in os.listdir(training_images_dir) if f.lower().endswith(_img_exts)
)
seed_image_name = _seed_candidates[0]
# `spice` is just a variable name for the SPICEData instance load_data()
# returns here — any name would work; we use `spice` throughout these
# notebooks as an intuitive nod to JuSPICE / SPICEData.
spice = load_data(os.path.join(training_images_dir, seed_image_name))

print('Starting Stable Diffusion generation...')
synth_spice_sdiff = spice.synth_generation.generate(
    config=config,
    input_dataset=dataset,
    method_name=method_name,
    repo_root=repo_root,
    N_images=N_images,
    device=device,
    force=force,
)
print(f'Generation complete! dataset_type={synth_spice_sdiff.dataset_type!r}, '
      f'n_frames={synth_spice_sdiff.n_frames}')
20:08:2026 18:25:50 - Generating synthetic images using Stable Diffusion model ...
20:08:2026 18:25:50 - Parameters for the Stable Diffusion model were set.
20:08:2026 18:25:50 - Initial parameters and file/folder paths were set.
20:08:2026 18:25:50 - Preprocessing training images...
Starting Stable Diffusion generation...
Preprocessing images: 100%|██████████| 10/10 [00:00<00:00, 354.33it/s]
20:08:2026 18:25:50 - Training images and masks were preprocessed.
20:08:2026 18:25:50 - Test images and masks were preprocessed.
20:08:2026 18:25:50 - *******************
20:08:2026 18:25:50 - Using device: mps for Stable Diffusion model.
Preprocessing complete.
Images saved to: /Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_images
Masks saved to: /Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_masks
[transformers] `Siglip2ImageProcessorFast` is deprecated. The `Fast` suffix for image processors has been removed; use `Siglip2ImageProcessor` instead.
20:08:2026 18:25:52 - Loading Stable Diffusion v1.5 model: runwayml/stable-diffusion-v1-5
20:08:2026 18:25:52 - ================================================================================
20:08:2026 18:25:52 - MODEL DOWNLOAD INFORMATION:
20:08:2026 18:25:52 -   • Model: runwayml/stable-diffusion-v1-5
20:08:2026 18:25:52 -   • Estimated size: ~5.1 GB
20:08:2026 18:25:52 -   • Cache location: /Users/amir/GIT_repositories/juspice_pre_release/Pretrained_models/stable_diffusion
20:08:2026 18:25:52 -   • First download may take 10-15 minutes depending on connection
20:08:2026 18:25:52 -   • Subsequent runs will use cached model (instant)
20:08:2026 18:25:52 -   • Progress shown below (fetching model files)...
20:08:2026 18:25:52 - ================================================================================
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/huggingface_hub/utils/_validators.py:189: UserWarning: The `resume_download` argument is deprecated and ignored in `from_pretrained`. Downloads always resume whenever possible.
  warnings.warn(
20:08:2026 18:25:52 - HTTP Request: GET https://huggingface.co/api/models/runwayml/stable-diffusion-v1-5 "HTTP/1.1 307 Temporary Redirect"
20:08:2026 18:25:52 - HTTP Request: GET https://huggingface.co/api/models/stable-diffusion-v1-5/stable-diffusion-v1-5 "HTTP/1.1 200 OK"
20:08:2026 18:25:52 - HTTP Request: HEAD https://huggingface.co/runwayml/stable-diffusion-v1-5/resolve/main/model_index.json "HTTP/1.1 307 Temporary Redirect"
20:08:2026 18:25:52 - HTTP Request: HEAD https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/resolve/main/model_index.json "HTTP/1.1 307 Temporary Redirect"
Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
20:08:2026 18:25:52 - Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
20:08:2026 18:25:52 - HTTP Request: HEAD https://huggingface.co/api/resolve-cache/models/stable-diffusion-v1-5/stable-diffusion-v1-5/451f4fe16113bff5a5d2269ed5ad43b0592e9a14/model_index.json "HTTP/1.1 200 OK"
20:08:2026 18:25:52 - HTTP Request: GET https://huggingface.co/api/models/runwayml/stable-diffusion-v1-5/revision/main "HTTP/1.1 307 Temporary Redirect"
20:08:2026 18:25:53 - HTTP Request: GET https://huggingface.co/api/models/stable-diffusion-v1-5/stable-diffusion-v1-5/revision/main "HTTP/1.1 200 OK"
Fetching 15 files: 100%|██████████| 15/15 [04:36<00:00, 18.44s/it]
Loading weights: 100%|██████████| 196/196 [00:00<00:00, 727.05it/s] 1.30s/it]
Loading weights: 100%|██████████| 396/396 [00:00<00:00, 688.29it/s] 1.47it/s]
Loading pipeline components...: 100%|██████████| 7/7 [00:03<00:00,  1.81it/s]
20:08:2026 18:30:33 - ✓ Successfully loaded runwayml/stable-diffusion-v1-5
20:08:2026 18:30:33 - Moving model to mps device...
20:08:2026 18:30:34 - ✓ Model ready on mps device.
20:08:2026 18:30:34 - Stable Diffusion model was initialized.
100%|██████████| 5/5 [00:02<00:00,  1.90it/s]
20:08:2026 18:30:39 - Generated 1 synthetic images for input image 1/10.
100%|██████████| 5/5 [00:00<00:00,  5.12it/s]
20:08:2026 18:30:48 - Generated 1 synthetic images for input image 2/10.
100%|██████████| 5/5 [00:00<00:00,  5.18it/s]
20:08:2026 18:30:55 - Generated 1 synthetic images for input image 3/10.
100%|██████████| 5/5 [00:00<00:00,  5.20it/s]
20:08:2026 18:31:01 - Generated 1 synthetic images for input image 4/10.
100%|██████████| 5/5 [00:00<00:00,  5.20it/s]
20:08:2026 18:31:08 - Generated 1 synthetic images for input image 5/10.
100%|██████████| 5/5 [00:00<00:00,  5.20it/s]
20:08:2026 18:31:15 - Generated 1 synthetic images for input image 6/10.
100%|██████████| 5/5 [00:00<00:00,  5.09it/s]
20:08:2026 18:31:22 - Generated 1 synthetic images for input image 7/10.
100%|██████████| 5/5 [00:00<00:00,  5.19it/s]
20:08:2026 18:31:29 - Generated 1 synthetic images for input image 8/10.
100%|██████████| 5/5 [00:00<00:00,  5.19it/s]
20:08:2026 18:31:36 - Generated 1 synthetic images for input image 9/10.
100%|██████████| 5/5 [00:00<00:00,  5.18it/s]
20:08:2026 18:31:42 - Generated 1 synthetic images for input image 10/10.
20:08:2026 18:31:48 - The synthetic images were generated.
20:08:2026 18:31:48 - The synthetic images were saved in the folder: /Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/SDiff_SiO2_lithiation
20:08:2026 18:31:48 - *******************
Generation complete! dataset_type='multiple_frames', n_frames=30
[9]:
tracker.recording_stop()
Inspect the results
Generated images (top) and the masks copied from their input images (bottom).
[10]:
tracker.recording_start()
[11]:
# --------- Block 3: Visualize generated images ----------

output_masks_dir = synth_spice_sdiff.metadata['masks_dir']
n_show = min(6, synth_spice_sdiff.n_frames)

fig, axes = plt.subplots(2, n_show, figsize=(18, 6))
fig.suptitle(
    'Stable Diffusion Generated Synthetic Images', fontsize=16, fontweight='bold'
)
for idx in range(n_show):
    img_data = synth_spice_sdiff.frames[idx]
    img_file = os.path.basename(synth_spice_sdiff.frame_paths[idx])
    mask_path = os.path.join(output_masks_dir, img_file)
    axes[0, idx].imshow(img_data, cmap='gray')
    axes[0, idx].axis('off')
    if os.path.exists(mask_path):
        mask_data = load_data(mask_path).data
        axes[1, idx].imshow(mask_data, cmap='gray')
    axes[1, idx].axis('off')
plt.tight_layout()
plt.show()
[12]:
tracker.recording_stop()
Save and review
We save the generated images and print the start of the recorded history.
[13]:
tracker.recording_start()
[14]:
# --------- Block 4: Save ----------

if synth_spice_sdiff.n_frames == 0:
    raise RuntimeError('No generated images found to export.')

# Writes <stem>.npy, <stem>.json, and <stem>_history.py next to the notebook
# This folder holds several notebooks, so save_data()'s automatic
# notebook-name detection would be ambiguous when run outside a live
# Jupyter session (e.g. via nbconvert) — pass output_stem explicitly
# to always land on this notebook's own files. See
# docs/repository_structure.rst.
stem = 'example_SDiff'
save_data(
    synth_spice_sdiff,
    output_stem=str(notebook_dir / stem),
)
print(f'Data:           {os.path.join(notebook_dir, stem + ".npy")}')
print(f'JSON sidecar:   {os.path.join(notebook_dir, stem + ".json")}')
print(f'History script: {os.path.join(notebook_dir, stem + "_history.py")}')
Data:           /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_SDiff.npy
JSON sidecar:   /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_SDiff.json
History script: /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_SDiff_history.py
[15]:
# --------- Block 5: Validate + Inspect human-readable history ----------

# synth_spice_sdiff.history.to_lines() reconstructs the full Stable Diffusion
# synthesis pipeline for this SPICEData object into readable, runnable code:
# the initial load_data(...) call followed by synth_generation.generate() and
# a trailing save_data(synth_spice_sdiff).
readable_lines = synth_spice_sdiff.history.to_lines()

print('Reconstructed synthesis pipeline for this SPICEData object:')
print('\n'.join(readable_lines[:6]), '...')
Reconstructed synthesis pipeline for this SPICEData object:
import juspice
import juspice.synth_data_module
spice = juspice.io.load_data('/Users/amir/GIT_repositories/juspice_pre_release/Sample_data/Train_test_images/SiO2_lithiation/images/train/2018-10-19_14_15_130.jpg')
spice = apply_stable_diff(spice, method='__init__', prompt='The input image is a grayscale electron microscopy image. Generate a visually similar electron microscopy image with comparable but random object shapes, such as round corners and edges, and similar background texture. Do not change the background (zero pixels in the mask) whatsoever.\n', width=320, height=320, device='mps', is_masked=False, cache_dir='/Users/amir/GIT_repositories/juspice_pre_release/Pretrained_models/stable_diffusion')
spice = apply_stable_diff(spice, method='stadiff_generate_synthetic_images', input_image_path='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_images/2018-10-19_14_15_136.jpg', synth_image_prefix='synth', output_dir='/Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/SDiff_SiO2_lithiation', num_images=1, guidance_scale=20, strength=0.1, mask_image_path='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_masks/2018-10-19_14_15_136.jpg', init_img_index=0)
spice = apply_stable_diff(spice, method='stadiff_generate_synthetic_images', input_image_path='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_images/2018-10-19_14_15_138.jpg', synth_image_prefix='synth', output_dir='/Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/SDiff_SiO2_lithiation', num_images=1, guidance_scale=20, strength=0.1, mask_image_path='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/SDiff_SiO2_lithiation/input_masks/2018-10-19_14_15_138.jpg', init_img_index=1) ...
[16]:
tracker.recording_stop()