Generating Microscopy Images with a GAN
Can a neural network learn what our microscopy images look like well enough to produce new ones? A generative adversarial network (GAN) tries to do exactly that.
This notebook trains a deep convolutional GAN (DCGAN) on frames of an in-situ TEM video of SiO₂ lithiation, generates new image–mask pairs, and checks the training curves to judge whether training worked.
JuSPICE Modules and Classes
juspice.io:SPICEData,load_data,save_datajuspice.synth_data_module:ConfigLoader,SynthGenerationAccessor(viaspice.synth_generation)juspice.tracking:Tracker
[1]:
from juspice.tracking import Tracker

tracker = Tracker(include_metadata=True, notes='DCGAN-based synthetic data generation')

tracker.recording_start()
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/tqdm/auto.py:21: TqdmWarning: IProgress not found. Please update jupyter and ipywidgets. See https://ipywidgets.readthedocs.io/en/stable/user_install.html
  from .autonotebook import tqdm as notebook_tqdm
[2]:
# --------- Block 0: Setup ----------

# Standard library
from pathlib import Path
import sys
import os
import json
import logging
import shutil

# Third-party
import numpy as np
import matplotlib.pyplot as plt
try:
    import torch
    _torch_available = True
except ImportError:
    torch = None
    _torch_available = False
    print("WARNING: torch is not installed. Device selection will default to 'cpu'.")

# JuSPICE
from juspice.io import SPICEData, load_data, save_data
from juspice.synth_data_module import ConfigLoader

# Paths
try:
    notebook_dir = Path(__file__).resolve().parent
except Exception:
    notebook_dir = Path.cwd()

cur = notebook_dir
repo_root = None
for _ in range(6):
    if (cur / 'juspice').exists() or (cur / 'pyproject.toml').exists():
        repo_root = cur
        break
    if cur.parent == cur:
        break
    cur = cur.parent
if repo_root is None:
    repo_root = notebook_dir
if str(repo_root) not in sys.path:
    sys.path.insert(0, str(repo_root))

# Logging configuration
logging.basicConfig(
    level=logging.INFO,
    format='%(asctime)s - %(levelname)s - %(message)s',
    datefmt='%Y-%m-%d %H:%M:%S',
)
[3]:
tracker.recording_stop()
Settings
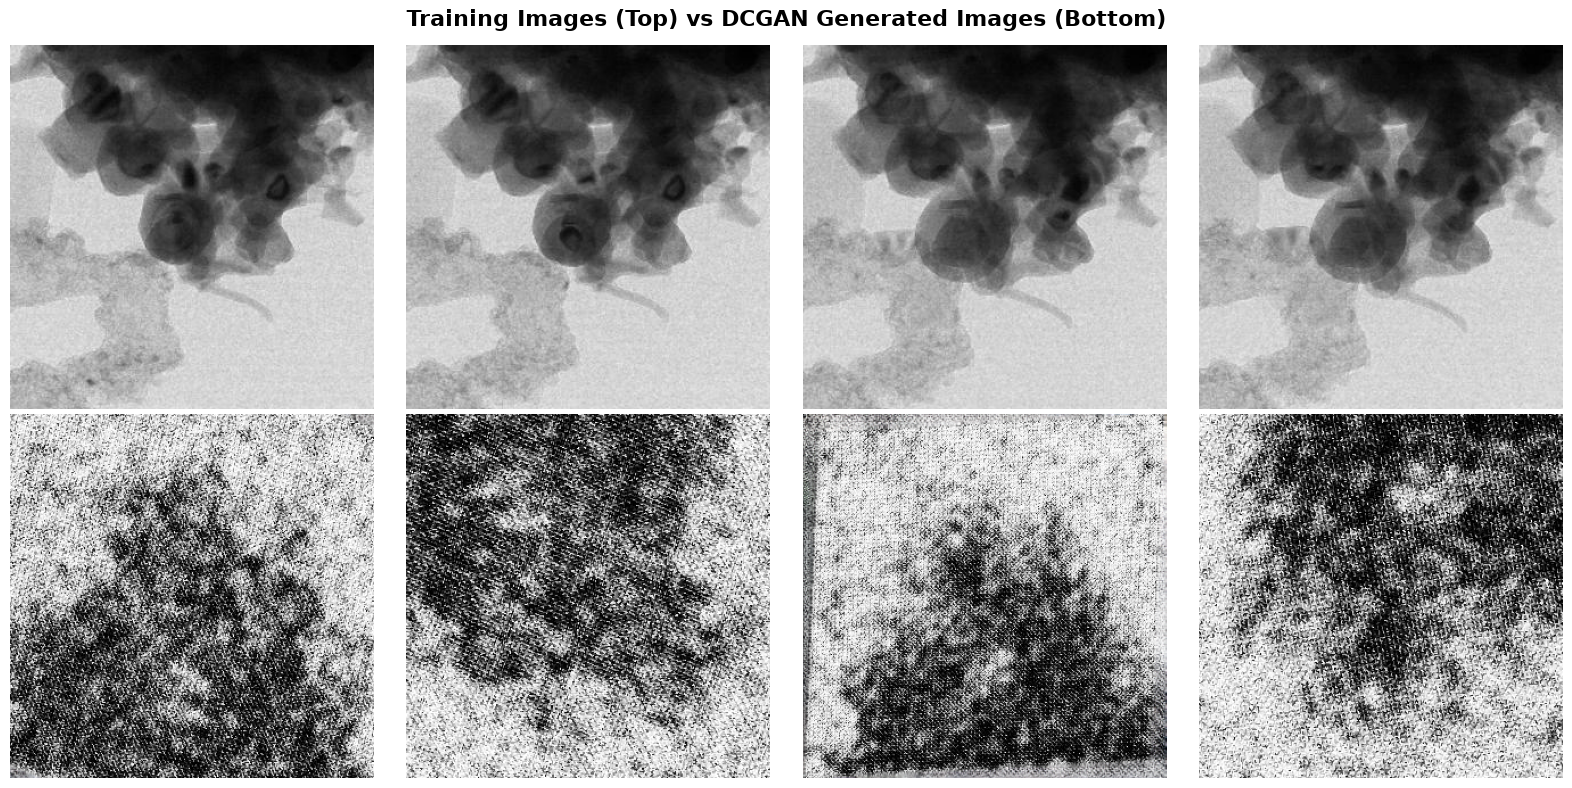
We choose a device and load the DCGAN parameters from notebooks_parameters.yaml. For a quick demo, this cell overrides a few of them: only 20 training epochs instead of 100, shorter early-stopping settings, and d_loss as the monitored curve. With so little training, the generated images are not expected to look fully realistic.
[4]:
tracker.recording_start()
[5]:
# --------- Block 1: Config and device ----------

_mps_available = (
    torch is not None
    and hasattr(torch.backends, 'mps')
    and torch.backends.mps.is_available()
)
if torch is not None and torch.cuda.is_available():
    device = 'cuda'
elif _mps_available:
    device = 'mps'
else:
    device = 'cpu'
logging.info(f'Using device: {device}.')

config_path = os.path.join(repo_root, 'notebooks', 'notebooks_parameters.yaml')
config = ConfigLoader(config_path)
logging.info(f'Configuration loaded from: {config_path}')

dataset = 'SiO2_lithiation'
method_name = 'DCGAN'
N_images = 10

# notebooks_parameters.yaml sets DCGAN.epochs=100 for real training runs;
# on CPU that took ~5s/epoch in testing (roughly 500s of training alone,
# plus preprocessing/generation overhead), close enough to nbconvert's
# 600s cell timeout to trip it. Override to a small epoch count here for
# a quick demo run — raise this (or remove the override) for real training,
# ideally on a GPU.
dcgan_params = config.get_gen_method_params(method_name)
dcgan_params['epochs'] = 20

# min_epoch_for_image (the warm-up floor before early stopping may fire)
# and early_stopping_patience must both fit inside the 20-epoch demo
# budget above — notebooks_parameters.yaml's real-training defaults
# (50 / 20) are sized for the full epochs=100 run. This run's own
# training curves consistently show the discriminator dominating
# (d_loss climbing, g_loss collapsing toward zero) rather than the
# generator collapsing, so d_loss -- not the conventional g_loss
# default -- is the signal actually worth watching here; monitoring
# g_loss would rarely stop early, since a collapsing generator's loss
# keeps falling every epoch, which looks like continuous improvement.
dcgan_params['min_epoch_for_image'] = 5
dcgan_params['early_stopping_patience'] = 5
dcgan_params['early_stopping_min_delta'] = 0.01
dcgan_params['early_stopping_monitor'] = 'd_loss'
20:08:2026 16:40:14 - Using device: mps.
20:08:2026 16:40:14 - Configuration loaded from: /Users/amir/GIT_repositories/juspice_pre_release/notebooks/notebooks_parameters.yaml
[6]:
tracker.recording_stop()
How a GAN learns
A GAN consists of two networks that compete (Goodfellow et al., 2014) [14]:
The generator turns a vector of random numbers into an image.
The discriminator looks at an image and estimates whether it is real or generated.
Training alternates between improving the discriminator at spotting fakes and improving the generator at fooling it. Ideally, the generator’s images eventually become so realistic that the discriminator can only guess.
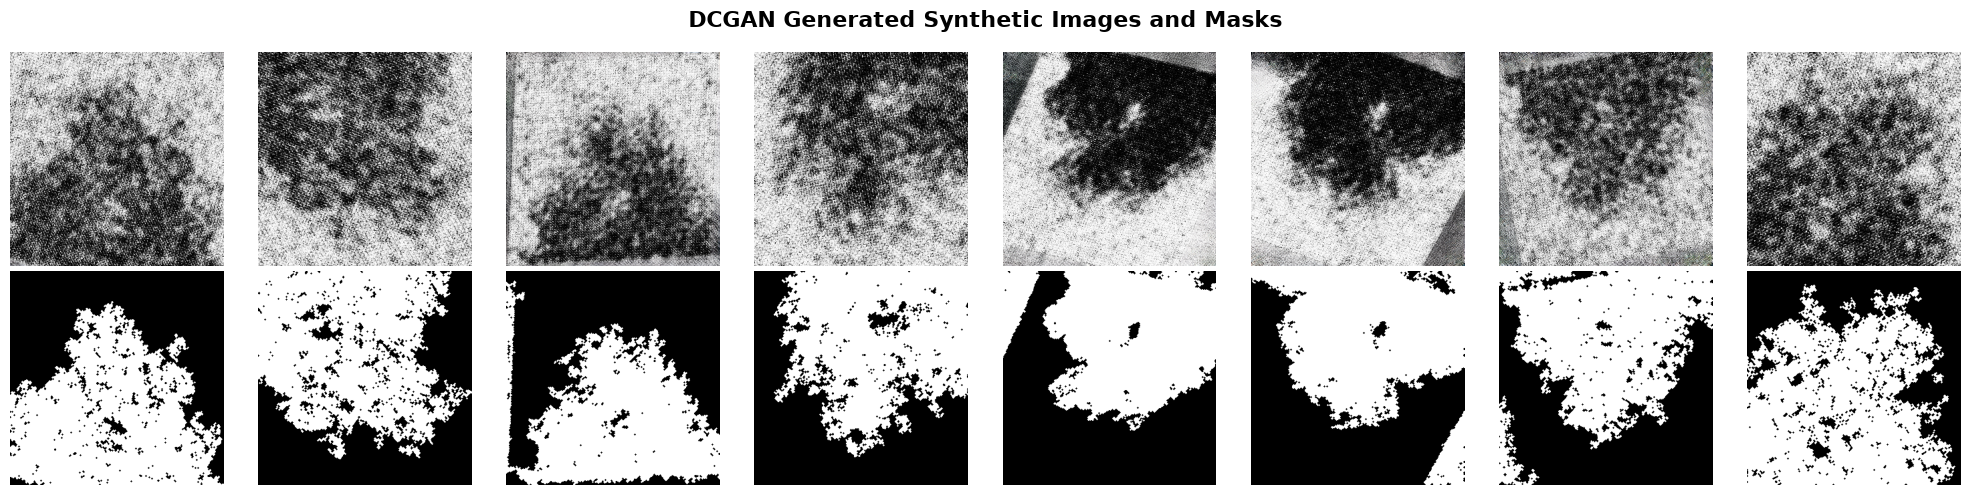
A DCGAN (Radford et al., 2015) [15] builds both networks from convolutional layers, which are well suited to images. latent_dim sets the length of the random input vector, and the filt_num* parameters set how many features each layer can learn. In JuSPICE, both networks work on image–mask pairs, so every generated image comes with a mask.
Reading the training curves
Three curves are saved during training:
Discriminator loss (
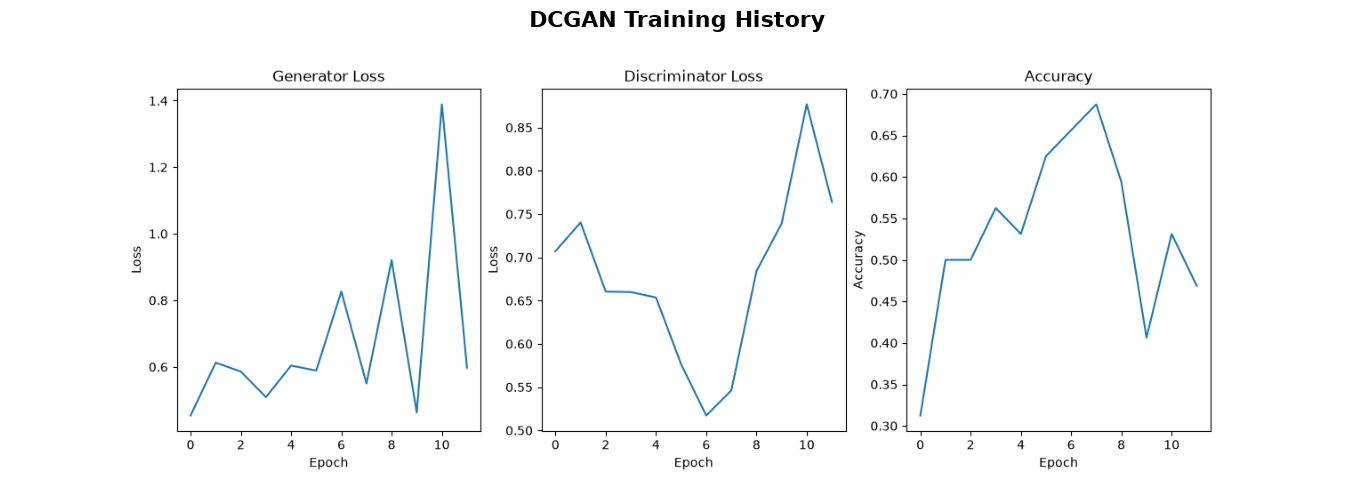
d_losses) and generator loss (g_losses). If the discriminator can only guess, both stay roughly near ln 2 ≈ 0.69 and fluctuate.Discriminator accuracy (
d_accuracies): about 50 % when the discriminator can only guess.
Warning signs are one loss dropping towards zero while the other rises, which means one network is clearly winning. A separate failure, mode collapse, is when the generator produces nearly identical images. It is best detected by looking at the generated samples, not the losses.
Early stopping
Training can stop before the last epoch if the monitored loss (early_stopping_monitor) has not improved by at least early_stopping_min_delta for early_stopping_patience epochs. It can only happen after min_epoch_for_image epochs. Training also stops at once if a loss becomes NaN or infinite. Progress messages are printed through Python’s logging.
We now load one training image as the starting point, then train the DCGAN and generate new images.
[7]:
tracker.recording_start()
[8]:
# --------- Block 2: Initialize and train ----------

# Load one training image as the SPICEData entry point / history anchor —
# spice.synth_generation.generate() doesn't transform spice.data itself
# (it produces a brand-new dataset), but the returned dataset shares this
# object's history lineage, so the provenance reads "generated from this
# reference training set".
dataset_params = config.get_dataset_params(dataset)
training_images_dir = os.path.join(repo_root, dataset_params['training_images_dir'])
_img_exts = ('.png', '.jpg', '.jpeg', '.tif', '.tiff')
_seed_candidates = sorted(
    f for f in os.listdir(training_images_dir) if f.lower().endswith(_img_exts)
)
seed_image_name = _seed_candidates[0]
# `spice` is just a variable name for the SPICEData instance load_data()
# returns here — any name would work; we use `spice` throughout these
# notebooks as an intuitive nod to JuSPICE / SPICEData.
spice = load_data(os.path.join(training_images_dir, seed_image_name))

print('Starting DCGAN training and generation...')
synth_spice_dcgan = spice.synth_generation.generate(
    config=config,
    input_dataset=dataset,
    method_name=method_name,
    repo_root=repo_root,
    N_images=N_images,
    device=device,
    analysis_level='synth_generation',
)
print(
    f'Training and generation complete! '
    f'dataset_type={synth_spice_dcgan.dataset_type!r}, '
    f'n_frames={synth_spice_dcgan.n_frames}'
)
20:08:2026 16:40:14 - Parameters for the DCGAN model were set.
20:08:2026 16:40:14 - Initial parameters and file/folder paths were set.
20:08:2026 16:40:14 - Preprocessing training images...
Starting DCGAN training and generation...
Preprocessing images: 100%|██████████| 10/10 [00:00<00:00, 333.51it/s]
20:08:2026 16:40:14 - Training images and masks were preprocessed.
20:08:2026 16:40:14 - *******************
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/keras/src/layers/convolutional/base_conv.py:113: UserWarning: Do not pass an `input_shape`/`input_dim` argument to a layer. When using Sequential models, prefer using an `Input(shape)` object as the first layer in the model instead.
  super().__init__(activity_regularizer=activity_regularizer, **kwargs)
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/keras/src/layers/activations/leaky_relu.py:41: UserWarning: Argument `alpha` is deprecated. Use `negative_slope` instead.
  warnings.warn(
20:08:2026 16:40:15 -
Discriminator Model Summary (Input: Image + Mask):
Preprocessing complete.
Images saved to: /Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_images
Masks saved to: /Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_masks
Model: "sequential"
┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┓
┃ Layer (type)                    ┃ Output Shape           ┃       Param # ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━┩
│ conv2d (Conv2D)                 │ (None, 160, 160, 32)   │           608 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu (LeakyReLU)         │ (None, 160, 160, 32)   │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_1 (Conv2D)               │ (None, 80, 80, 64)     │        18,496 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ zero_padding2d (ZeroPadding2D)  │ (None, 81, 81, 64)     │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_1 (LeakyReLU)       │ (None, 81, 81, 64)     │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_2 (Conv2D)               │ (None, 41, 41, 128)    │        73,856 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_2 (LeakyReLU)       │ (None, 41, 41, 128)    │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_3 (Conv2D)               │ (None, 41, 41, 320)    │       368,960 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_3 (LeakyReLU)       │ (None, 41, 41, 320)    │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ flatten (Flatten)               │ (None, 537920)         │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ dense (Dense)                   │ (None, 1)              │       537,921 │
└─────────────────────────────────┴────────────────────────┴───────────────┘
Total params: 999,841 (3.81 MB)
Trainable params: 999,841 (3.81 MB)
Non-trainable params: 0 (0.00 B)
/Users/amir/GIT_repositories/juspice_pre_release/venvs/.venv/lib/python3.12/site-packages/keras/src/layers/core/dense.py:107: UserWarning: Do not pass an `input_shape`/`input_dim` argument to a layer. When using Sequential models, prefer using an `Input(shape)` object as the first layer in the model instead.
  super().__init__(activity_regularizer=activity_regularizer, **kwargs)
20:08:2026 16:40:15 -
Generator Model Summary (Image + Mask):
Model: "sequential_1"
┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┓
┃ Layer (type)                    ┃ Output Shape           ┃       Param # ┃
┡━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━┩
│ dense_1 (Dense)                 │ (None, 819200)         │    82,739,200 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ reshape (Reshape)               │ (None, 80, 80, 128)    │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_transpose                │ (None, 160, 160, 128)  │       147,584 │
│ (Conv2DTranspose)               │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ batch_normalization             │ (None, 160, 160, 128)  │           512 │
│ (BatchNormalization)            │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_4 (LeakyReLU)       │ (None, 160, 160, 128)  │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_transpose_1              │ (None, 320, 320, 64)   │        73,792 │
│ (Conv2DTranspose)               │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ batch_normalization_1           │ (None, 320, 320, 64)   │           256 │
│ (BatchNormalization)            │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_5 (LeakyReLU)       │ (None, 320, 320, 64)   │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ dropout (Dropout)               │ (None, 320, 320, 64)   │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_4 (Conv2D)               │ (None, 320, 320, 64)   │        36,928 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ batch_normalization_2           │ (None, 320, 320, 64)   │           256 │
│ (BatchNormalization)            │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_6 (LeakyReLU)       │ (None, 320, 320, 64)   │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_5 (Conv2D)               │ (None, 320, 320, 64)   │        36,928 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ batch_normalization_3           │ (None, 320, 320, 64)   │           256 │
│ (BatchNormalization)            │                        │               │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ leaky_re_lu_7 (LeakyReLU)       │ (None, 320, 320, 64)   │             0 │
├─────────────────────────────────┼────────────────────────┼───────────────┤
│ conv2d_6 (Conv2D)               │ (None, 320, 320, 2)    │         1,154 │
└─────────────────────────────────┴────────────────────────┴───────────────┘
Total params: 83,036,866 (316.76 MB)
Trainable params: 83,036,226 (316.76 MB)
Non-trainable params: 640 (2.50 KB)
20:08:2026 16:40:15 -
Starting training from scratch
20:08:2026 16:40:28 - Epoch 0 [D loss: 0.7071 | D acc: 31.25%] [G loss: 0.4537]
20:08:2026 16:40:28 -   real_scores: [0.7730182 0.7726498 0.7859404 0.7837749 0.7788735 0.7788735 0.7859404
 0.7730182]
20:08:2026 16:40:28 -   fake_scores: [0.53096    0.5213578  0.5345942  0.5404787  0.5407821  0.5305763
 0.53281546 0.5322729 ]
20:08:2026 16:40:37 - Epoch 1 [D loss: 0.7403 | D acc: 50.00%] [G loss: 0.6126]
20:08:2026 16:40:44 - Epoch 2 [D loss: 0.6604 | D acc: 50.00%] [G loss: 0.5858]
20:08:2026 16:40:52 - Epoch 3 [D loss: 0.6598 | D acc: 56.25%] [G loss: 0.5089]
20:08:2026 16:40:59 - Epoch 4 [D loss: 0.6536 | D acc: 53.12%] [G loss: 0.6038]
20:08:2026 16:41:06 - Epoch 5 [D loss: 0.5765 | D acc: 62.50%] [G loss: 0.5888]
20:08:2026 16:41:14 - Epoch 6 [D loss: 0.5172 | D acc: 65.62%] [G loss: 0.8264]
20:08:2026 16:41:21 - Epoch 7 [D loss: 0.5462 | D acc: 68.75%] [G loss: 0.5498]
20:08:2026 16:41:28 - Epoch 8 [D loss: 0.6842 | D acc: 59.38%] [G loss: 0.9210]
20:08:2026 16:41:35 - Epoch 9 [D loss: 0.7391 | D acc: 40.62%] [G loss: 0.4627]
20:08:2026 16:41:42 - Epoch 10 [D loss: 0.8770 | D acc: 53.12%] [G loss: 1.3892]
20:08:2026 16:41:50 - Epoch 11 [D loss: 0.7641 | D acc: 46.88%] [G loss: 0.5971]
20:08:2026 16:41:50 - Early stopping at epoch 11: d_loss has not improved by at least 0.01 for 5 epochs (best=0.5172).
20:08:2026 16:41:50 - DCGAN model was trained.
20:08:2026 16:41:50 - Training history was plotted and saved.
20:08:2026 16:41:50 - Generating 5 synthetic images ...
20:08:2026 16:41:50 - No checkpoint found. Using current generator.
Generating synthetic images: 100%|██████████| 5/5 [00:00<00:00, 412.54it/s]
20:08:2026 16:41:50 -
Saved 5 synthetic images to /Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/DCGAN_SiO2_lithiation/images
20:08:2026 16:41:50 - Saved 5 masks to /Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/DCGAN_SiO2_lithiation/masks
20:08:2026 16:41:50 - Synthetic data generation completed.
Generating augmented images: 100%|██████████| 5/5 [00:30<00:00,  6.09s/it]
20:08:2026 16:42:20 - Synthetic image and masks were generated and saved.
Training and generation complete! dataset_type='multiple_frames', n_frames=10
[9]:
tracker.recording_stop()
Inspect the results
The first figure shows the training curves; the second shows generated images with their masks.
[10]:
tracker.recording_start()
[11]:
# --------- Block 3: Visualize training history and generated images ----------

output_images_dir = os.path.dirname(synth_spice_dcgan.frame_paths[0])
synth_images_dir = os.path.dirname(output_images_dir)
output_masks_dir = synth_spice_dcgan.metadata['masks_dir']
history_plot_path = os.path.join(synth_images_dir, 'training_history.png')

if os.path.exists(history_plot_path):
    history_img = load_data(history_plot_path).data
    plt.figure(figsize=(15, 5))
    plt.imshow(history_img)
    plt.axis('off')
    plt.title('DCGAN Training History', fontsize=16, fontweight='bold')
    plt.tight_layout()
    plt.show()

n_show = min(8, synth_spice_dcgan.n_frames)
fig, axes = plt.subplots(2, n_show, figsize=(20, 5))
fig.suptitle(
    'DCGAN Generated Synthetic Images and Masks', fontsize=16, fontweight='bold'
)
for idx in range(n_show):
    img_data = synth_spice_dcgan.frames[idx]
    img_file = os.path.basename(synth_spice_dcgan.frame_paths[idx])
    mask_path = os.path.join(output_masks_dir, img_file)
    axes[0, idx].imshow(img_data, cmap='gray')
    axes[0, idx].axis('off')
    if os.path.exists(mask_path):
        mask_data = load_data(mask_path).data
        axes[1, idx].imshow(mask_data, cmap='gray')
    axes[1, idx].axis('off')
plt.tight_layout()
plt.show()
[12]:
tracker.recording_stop()
Placing real training images (top) next to generated ones (bottom) makes it easier to judge how realistic the generated texture is.
[13]:
tracker.recording_start()
[14]:
# --------- Block 4: Compare training vs generated ----------

input_images_dir = synth_spice_dcgan.metadata['input_images_preprocessed_dir']
input_files = sorted(
    f for f in os.listdir(input_images_dir)
    if f.lower().endswith(('.jpeg', '.jpg', '.png', '.tif', '.tiff'))
)[:4]
n_show4 = min(4, synth_spice_dcgan.n_frames)

fig, axes = plt.subplots(2, 4, figsize=(16, 8))
fig.suptitle(
    'Training Images (Top) vs DCGAN Generated Images (Bottom)',
    fontsize=16, fontweight='bold',
)
for idx, img_file in enumerate(input_files):
    img_path = os.path.join(input_images_dir, img_file)
    img_data = load_data(img_path).data
    axes[0, idx].imshow(img_data, cmap='gray')
    axes[0, idx].axis('off')
for idx in range(n_show4):
    img_data = synth_spice_dcgan.frames[idx]
    axes[1, idx].imshow(img_data, cmap='gray')
    axes[1, idx].axis('off')
plt.tight_layout()
plt.show()
[15]:
tracker.recording_stop()
Check convergence and save
The slope of the discriminator loss over the last 50 recorded values shows whether it is still changing. We then save the generated images with their history.
[16]:
tracker.recording_start()
[17]:
# --------- Block 5: Inspect convergence and save ----------

models_dir = synth_spice_dcgan.metadata['synth_models_dir']
paths = {
    'd_losses': os.path.join(models_dir, 'd_losses.npy'),
    'g_losses': os.path.join(models_dir, 'g_losses.npy'),
    'd_acc': os.path.join(models_dir, 'd_accuracies.npy'),
}
missing = [k for k, p in paths.items() if not os.path.exists(p)]
if missing:
    print(f'Missing histories for: {missing}')
else:
    d_losses = np.load(paths['d_losses'])
    g_losses = np.load(paths['g_losses'])
    d_acc = np.load(paths['d_acc'])
    d_tail = d_losses[-50:]
    d_trend = np.polyfit(range(len(d_tail)), d_tail, 1)[0]
    print(f'D loss trend (last 50): {d_trend:.4f}')

if synth_spice_dcgan.n_frames == 0:
    raise RuntimeError('No generated images found to export.')

# Writes <stem>.npy, <stem>.json, and <stem>_history.py next to the notebook
# This folder holds several notebooks, so save_data()'s automatic
# notebook-name detection would be ambiguous when run outside a live
# Jupyter session (e.g. via nbconvert) — pass output_stem explicitly
# to always land on this notebook's own files. See
# docs/repository_structure.rst.
stem = 'example_DCGAN'
save_data(
    synth_spice_dcgan,
    output_stem=str(notebook_dir / stem),
)
print(f'Data:           {os.path.join(notebook_dir, stem + ".npy")}')
print(f'JSON sidecar:   {os.path.join(notebook_dir, stem + ".json")}')
print(f'History script: {os.path.join(notebook_dir, stem + "_history.py")}')
D loss trend (last 50): 0.0075
Data:           /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_DCGAN.npy
JSON sidecar:   /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_DCGAN.json
History script: /Users/amir/GIT_repositories/juspice_pre_release/notebooks/synthetic_data/example_DCGAN_history.py
[18]:
# --------- Block 7: Validate + Inspect human-readable history ----------

# synth_spice_dcgan.history.to_lines() reconstructs the full DCGAN synthesis
# pipeline for this SPICEData object into readable, runnable code: the initial
# load_data(...) call followed by synth_generation.generate() and
# a trailing save_data(synth_spice_dcgan).
readable_lines = synth_spice_dcgan.history.to_lines()

print('Reconstructed synthesis pipeline for this SPICEData object:')
print('\n'.join(readable_lines[:6]), '...')
Reconstructed synthesis pipeline for this SPICEData object:
import juspice
import juspice.synth_data_module
spice = juspice.io.load_data('/Users/amir/GIT_repositories/juspice_pre_release/Sample_data/Train_test_images/SiO2_lithiation/images/train/2018-10-19_14_15_130.jpg')
spice = apply_dcgan(spice, method='__init__', img_folder='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_images', mask_folder='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_masks', img_shape=[320, 320, 1], latent_dim=100, batch_size=16, epochs=20, learning_rate=0.0001, beta_1=0.5, checkpoint_dir='/Users/amir/GIT_repositories/juspice_pre_release/Models/synth_models/DCGAN_SiO2_lithiation', sample_interval=100, min_epoch_for_image=5, early_stopping_patience=5, early_stopping_min_delta=0.01, early_stopping_monitor='d_loss', trained_model_dir='/Users/amir/GIT_repositories/juspice_pre_release/Models/synth_models/DCGAN_SiO2_lithiation', filt_num_generator=[128, 128, 64], filt_num_discriminator=[32, 64, 128, 320], kernel_size=3, strides=2, original_shape=[1024, 1024, 1])
spice = apply_dcgan(spice, method='train', img_folder='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_images', mask_folder='/Users/amir/GIT_repositories/juspice_pre_release/preprocessed_data/DCGAN_SiO2_lithiation/input_masks', img_shape=[320, 320, 1], latent_dim=100, batch_size=16, epochs=20, epochs_completed=12, learning_rate=0.0001, beta_1=0.5, checkpoint_dir='/Users/amir/GIT_repositories/juspice_pre_release/Models/synth_models/DCGAN_SiO2_lithiation', min_epoch_for_image=5, early_stopping_patience=5, early_stopping_min_delta=0.01, early_stopping_monitor='d_loss')
spice = apply_dcgan(spice, method='dcgan_generate_synthetic_images_and_masks', synth_images_dir='/Users/amir/GIT_repositories/juspice_pre_release/Synthetic_images/DCGAN_SiO2_lithiation', num_samples=5) ...
[19]:
tracker.recording_stop()